
Being #1 Barely Matters in ChatGPT. Here Is the Math.


TL;DR
- ChatGPT doesn't run your question. It runs its own. One prompt fans out into roughly nine invisible sub-queries on average (Nectiv, 60,000+ fan-outs analyzed, 2026), and up to 28 on Gemini 3 (Seer Interactive, 501 prompts, 2026).
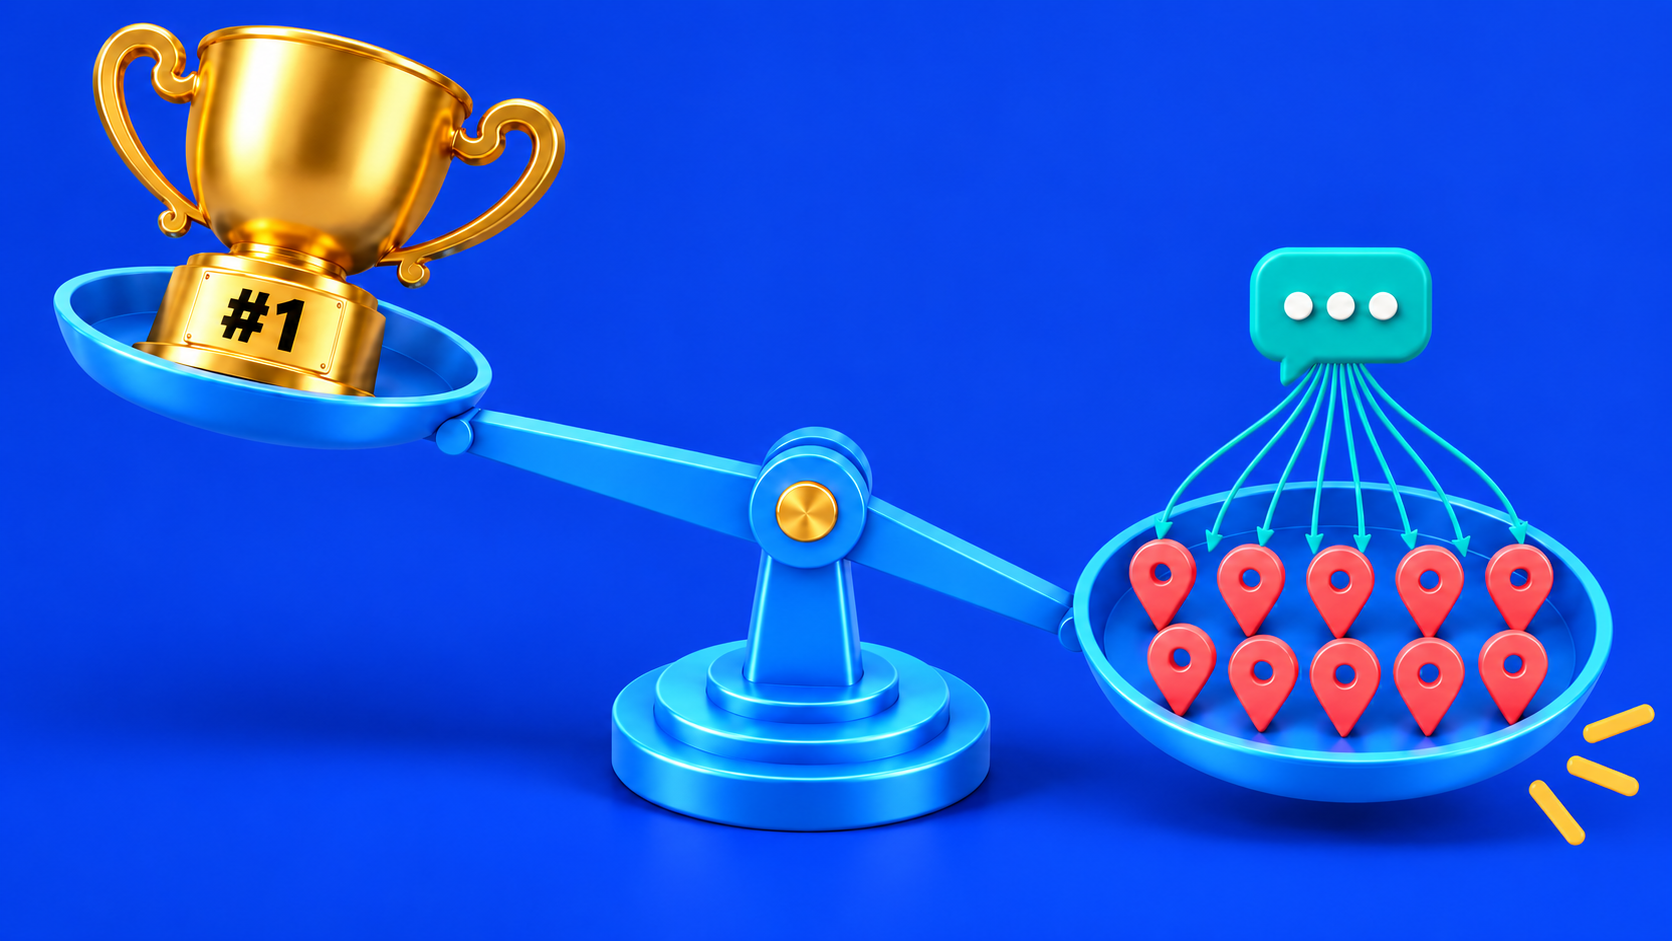
- The results are merged with Reciprocal Rank Fusion (RRF): an algorithm identified inside ChatGPT's citation ranking by researcher Metehan Yesilyurt (July 2025). The math: a mid-table presence across ten related sub-queries can outweigh a single #1 by roughly a factor of eight.
- More striking still: the engines now write brand names into their own searches. ChatGPT 5.5's fan-outs increasingly contain brands directly (Seer Interactive, 617 prompts, 2026). When that happens, you're no longer competing inside the answer: you are what's being searched for.
- That is narrative authority in its most literal, measurable form: being present enough across third-party sources that the engine summons you on its own.
What actually happens between your question and ChatGPT's answer?
A search you never see. When a user asks a generative engine a question ("best project management tools", "which agency for AI search") the model doesn't execute that query as typed. It rewrites it into a bundle of sub-queries covering the angles it considers relevant: comparisons, reviews, pricing, specific brand names, the current year. It runs them in parallel, gathers the ranked results of each, and fuses everything into the single answer the user reads. Those background searches are the fan-out queries.
The measured scale of this hidden layer:
Two properties make this layer strategically invisible to classic SEO. The queries are written by the machine at runtime (in shorthand no human types ("Pipedrive pricing 2026 plans")) so about 95% of them carry zero volume in any keyword tool. And they are unstable: Seer Interactive measured just 0.1% overlap in fan-outs between runs of the same prompt on Gemini 3. Your keyword tracker literally cannot see the searches that decide your AI visibility.
What is Reciprocal Rank Fusion, and why does it dethrone #1?
RRF is the merge step, and it changes what "winning" means. In July 2025, GEO researcher Metehan Yesilyurt (Peec AI) inspected ChatGPT's code and identified Reciprocal Rank Fusion as the algorithm merging results across sub-queries. RRF itself is not new: it's documented in information-retrieval literature since 2009. The finding was that it's running inside ChatGPT.
The formula is disarmingly simple. For each fan-out query where your page appears, it earns:
score = 1 / (k + rank), with k ≈ 60. The scores are then summed across all sub-queries.
Now run the numbers:
- A single #1 ranking on one query: 1 / (60 + 1) = 0.0164
- Rank ~20 across ten related sub-queries: 10 × 1 / (60 + 20) = 0.125, roughly 8x more
- Rank ~5 across ten sub-queries: 10 × 1 / (60 + 5) = 0.154, nearly 10x more
Because k = 60 dampens the gap between positions, the difference between rank 1 and rank 20 within one query is small, while every additional query you appear in adds a full new term to your sum. The conclusion is mathematical, not rhetorical: excellence on one angle loses to presence on all the angles. The correlation data backs it up: pages covered by fan-out queries were 161% more likely to be cited, with a 0.77 correlation between fan-out coverage and AI Overview citations (Surfer SEO, 2026).
Provocative? No. It's arithmetic.
The more troubling finding: brands inside the fan-outs themselves
The engines have started writing brand names into their own searches. Seer Interactive's research on ChatGPT 5.5 (Wil Reynolds and Nick Haigler, 617 prompts covering questions a CMO or VP of Growth would ask, June 2026) documents the shift: where fan-outs used to read "top GEO agencies", they increasingly read "[specific agency] GEO research". The generic category query is giving way to named-entity queries the model generates spontaneously: brands that were never in the user's prompt.
On Gemini 3, Seer measured it directly: 26.4% of fan-out queries included a brand name (501 prompts, 2026). And when Seer re-ran a single agency-selection prompt 30 times on ChatGPT 5.5, one firm (iPullRank) appeared in the fan-outs 97% of the time, and its founder Mike King 63% of the time. Years of publishing a consistent, recognizable point of view had hardwired that entity to that topic in the model's head.
Read what that means slowly.
When your brand is inside the fan-out, you are no longer one candidate competing inside the answer. You are the search. The engine has already decided you belong to this category: it's now looking for material about you to build its response.
You're not in the result. You are the result.
This is exactly what we mean by narrative authority, in its most literal, measurable form: being present enough, consistently enough, across third-party sources that the engine summons you spontaneously. Not because you ranked. Because you're hardwired. It's the same mechanism we saw from the buyer's side in our analysis of the Semrush B2B data: models learn category membership from co-occurrence across independent sources (reviews, publishers, expert coverage) not from what a brand says about itself.
SEO optimizes what you see. GEO plays out where you don't.
Let's be precise, because the nuance is the expertise. Fan-out queries are still searches. They still hit indexes where structure, crawlability and ranking fundamentals decide who surfaces, which is why the SEO foundation remains necessary. Ranking well feeds the fan-outs. It is simply no longer sufficient, because the unit of competition has changed:
- SEO optimizes the one query you can see: the star keyword in your tracker, with its volume and its position.
- GEO plays out across the ten or twenty queries you can't: machine-written, zero-volume, unstable between runs, and merged by an algorithm that rewards breadth and repetition over a single peak.
The pattern I find in most GEO diagnostics is exactly this blind spot: brands that have spent years perfecting their star query, and ignore the other angles the engines actually search. A pattern our own monitoring keeps confirming: across the questions we track daily on ChatGPT, Google AI Mode and AI Overviews, the sources cited vary heavily from run to run and from angle to angle: the brands that persist across that volatility are the ones present on many angles through many independent sources, never the ones with a single perfectly optimized page.
How do you cover the queries you're ignoring?
Three moves, in order, and both sides of the signal.
- Map the fan-outs of your category. Capture what the engines actually search when your buyers' questions come in: the comparisons, the "vs" queries, the pricing angles, the year-stamped variants, the adjacent how-tos. Several tools now expose fan-outs directly. This is your real keyword universe: the one with zero search volume and all the influence.
- Build coverage, not a hero page. One definitive page per angle beats one exhaustive page for the head term. Under RRF, a topic cluster that surfaces mid-table across ten sub-queries mathematically outweighs a single #1. Structure each page to be extractable: self-contained sections, front-loaded claims. 44.2% of LLM citations come from the first 30% of content (Growth Memo, Feb. 2026).
- Get written into the fan-outs through third parties. The brand-in-fan-out effect isn't triggered by your own site. It's triggered by co-occurrence: your name appearing next to your category, repeatedly, across independent sources. That's off-site authority building: reviews, sector press, expert citations, comparisons that name you among your peers. 85% of brand mentions in AI answers already come from third-party sources (AirOps, 2025); the fan-out data shows those same sources are what teaches the model to search for you by name.
One caveat, because credibility demands it: fan-out behavior differs across engines (Gemini 3 runs roughly five times more sub-queries than ChatGPT (Seer Interactive, 2026)) and these mechanisms are reverse-engineered observations of moving systems, not published specifications. Treat the numbers as solid orders of magnitude, revisit them quarterly, and never build a strategy on a single engine's quirks. The principle, however, is stable across all of them: fusion rewards presence across angles.
The question that actually matters
Every time someone asks an AI engine about your category (the moment we located in the new address of the purchase decision), the engine writes its dozen searches and fuses the results. That process runs whether you participate in it or not.
So the real question is no longer "do we rank #1?"
It's: when your category generates its fan-outs, are you in them?
FAQ
What is a query fan-out in AI search?
The set of additional searches an AI engine runs invisibly after one user prompt: the model rewrites the question into multiple sub-queries, runs them in parallel, and synthesizes one answer from the merged results. Averages: ~9 per ChatGPT prompt (Nectiv, 2026), 10.7 on Gemini 3 with peaks of 28 (Seer Interactive, 2026). About 95% carry zero search volume.
What is Reciprocal Rank Fusion (RRF)?
A ranking algorithm from information-retrieval research (documented since 2009) that merges result lists from multiple queries by scoring each page 1/(k + rank), with k ≈ 60, summed across queries. Metehan Yesilyurt identified it inside ChatGPT's citation ranking in July 2025.
Why does ranking #1 matter less in ChatGPT than in Google?
Because the answer is fused from many sub-queries. A single #1 scores 1/61 ≈ 0.0164 under RRF; a rank-20 presence across ten sub-queries scores 0.125, roughly eight times more. Breadth across the angles the engine searches beats a single visible peak.
How does a brand get written into AI fan-out queries?
Through category co-occurrence built off-site: repeated, consistent third-party presence (reviews, expert coverage, comparisons naming you among your peers) teaches the model that your entity belongs to the category. Seer Interactive found 26.4% of Gemini 3 fan-outs include a brand name, and one consistently published firm appeared in ChatGPT 5.5's fan-outs 97% of the time across 30 runs of the same prompt (2026).
------
HOW THIS WAS WRITTEN: Topic, angle, convictions: mine. AI assists the writing. I make the call.
Sabrina Bulteau is the co-founder of PingPrime.ai, GEO Expert and specialist in Narrative Authority in AI Search. She helps brands, institutions and media become the reference AI engines trust, cite, and repeat (not just one option among many) by working both sides of the signal: on-site (structure, narratives, architecture) and off-site (earned media, platforms, co-citations, sector press). Co-founder of Be Connect (acquired by iO Group) and Sench, active within CEC Belgium, she brings 25 years of experience in digital growth and strategic positioning.

